How Time Series Forecasting Works
Photo: Kampus Production / Pexels
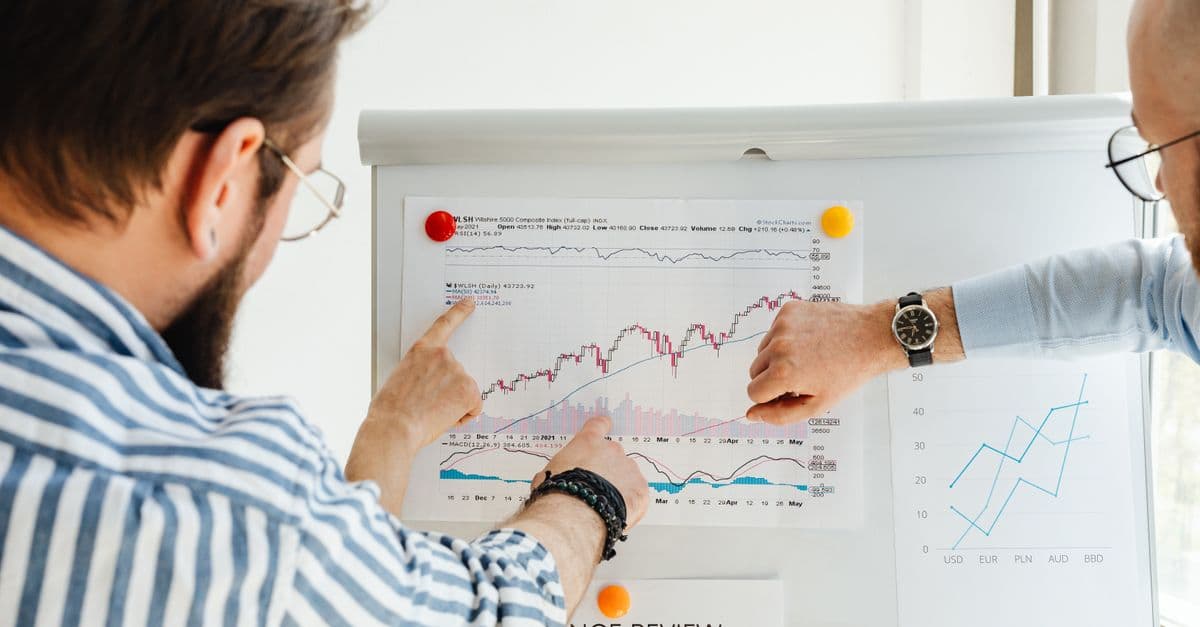
Retail chains restock winter coats in September and lawn furniture in February, months before demand shows up in daily sales. That timing isn't guesswork. It comes from decomposing years of past sales data into a predictable seasonal pattern, a long-term trend, and short-term noise, then projecting the first two forward while treating the third as fundamentally unknowable. Time series forecasting is the discipline behind that decision, and understanding how it actually works, where it comes from statistically, and where it reliably breaks down explains a lot about why some predictions age well and others collapse the moment reality changes shape.
What a time series actually is, and why order matters
A time series is a sequence of data points indexed in time order: daily temperature readings, monthly unemployment figures, hourly electricity load, or a company's quarterly revenue. What separates a time series from an ordinary dataset is that the order of the observations carries information. Shuffle a spreadsheet of customer ages and you lose nothing meaningful; shuffle a year of daily sales figures and you destroy the very structure a forecasting model depends on.
That dependence on order is what makes time series analysis a distinct branch of statistics rather than a subset of general regression. In ordinary regression, the assumption is that observations are independent of one another. In a time series, today's value is often correlated with yesterday's value, a property called autocorrelation — the tendency of a series to resemble a delayed copy of itself. Retail sales today look more like retail sales yesterday than like retail sales chosen at random from history, and that resemblance is exactly the signal forecasting models are built to exploit.
Time series data generally comes in one of two flavors. A univariate series tracks a single variable over time, like a single store's daily foot traffic. A multivariate series tracks several related variables simultaneously, like temperature, day of week, and promotional spend alongside sales, allowing a model to account for known external drivers rather than treating every fluctuation as internal to the series itself. Modern forecasting increasingly leans multivariate, because a model that knows a holiday is coming next Tuesday will beat one that has to infer it purely from the shape of past data.
It's also worth being precise about what forecasting promises and what it doesn't. A forecast is a statement about the most likely future value, wrapped in an estimate of how confident that statement is. It is not a guarantee, and treating a forecast as certainty rather than a probability distribution is one of the most common ways organizations get burned by their own models, a point this article returns to later.
Breaking a series into trend, seasonality, and noise
Every time series forecasting method starts from roughly the same core idea: decompose historical data into components that behave predictably and one component that doesn't. The classical decomposition splits a series into four elements — trend, seasonality, cyclical variation, and residual noise — though many practical treatments collapse the first three into "systematic pattern" and treat the fourth as everything left over.
Trend captures the slow, sustained direction of the series, independent of any particular month or day. A company's revenue growing roughly 5 percent year over year regardless of season is a trend. Seasonality captures a pattern that repeats at a fixed, known period, like ice cream sales peaking every July or web traffic dipping every weekend. The key distinguishing feature of seasonality is that its period is fixed and calendar-driven, which is what makes it forecastable in the first place.
Cyclical variation looks similar to seasonality on a chart but differs in one important way: cycles don't have a fixed period. Business cycles of expansion and recession, for instance, recur roughly every several years, but not on a schedule you can set a calendar to, which makes them far harder to forecast than calendar-locked seasonality. Many introductory treatments fold cyclical variation into "trend" for simplicity, but the distinction matters in industries like construction and manufacturing, where multi-year cycles genuinely differ from annual seasonality in both cause and predictability.
Once trend, seasonality, and cyclical effects are separated out mathematically, using methods like classical decomposition, STL (Seasonal-Trend decomposition using Loess), or moving-average smoothing, what remains is the residual, the leftover variation that no systematic pattern explains. This is the part a good forecasting model is not supposed to predict. A model that appears to fit the residual almost perfectly on historical data is usually not brilliant, it's overfit, meaning it has learned the specific noise of that particular sample rather than a pattern that will recur. The honest goal of decomposition isn't to eliminate the residual; it's to correctly extract everything that actually is predictable, leaving behind only the part that genuinely isn't.
The classical statistical toolkit: ARIMA and Box-Jenkins
ARIMA (AutoRegressive Integrated Moving Average) is the workhorse of classical time series forecasting, formalized by statisticians George Box and Gwilym Jenkins in their 1970 textbook Time Series Analysis: Forecasting and Control. ARIMA models a value as a function of its own past values (the autoregressive part), the differencing needed to make the series stationary (the integrated part), and past forecast errors (the moving average part). It remains a standard baseline in economics, demand planning, and finance because it is interpretable, computationally light, and performs well on data with a clear, stable pattern.
The letters in ARIMA correspond to three parameters, conventionally written (p, d, q). p is the number of lagged observations included, or how far back the model looks at its own past values. d is the number of times the raw data is differenced (subtracting each value from the one before it) to remove trend and achieve stationarity. q is the size of the moving-average window, or how many past forecast errors the model factors in. Choosing these three numbers correctly is most of the craft of building a good ARIMA model, and getting them wrong is the most common way an ARIMA forecast goes bad even when the underlying method is sound.
Why stationarity matters so much
Stationarity — a real, mathematically grounded property here — means a time series' statistical characteristics, such as its mean and variance, don't change over time. Most classical forecasting methods, ARIMA included, assume the series is stationary or can be made stationary through differencing, because a model trained to predict a fixed statistical structure has nothing to grab onto if that structure keeps shifting underneath it. A series with a clear upward trend is not stationary; differencing it once (looking at period-over-period changes instead of raw levels) often removes the trend and gets the model closer to a stable pattern it can actually learn.
The Box-Jenkins methodology, step by step
Box and Jenkins didn't just define ARIMA's structure, they proposed a systematic three-stage procedure for fitting it: identification, estimation, and diagnostic checking. Identification means examining the data (often via autocorrelation and partial autocorrelation plots) to propose reasonable values for p, d, and q. Estimation means fitting the chosen model's parameters to the historical data, typically via maximum likelihood. Diagnostic checking means examining the residuals of the fitted model to confirm they resemble random noise rather than a leftover pattern the model missed; if the residuals still show structure, the analyst cycles back to identification and tries a different specification. This iterative loop, still taught in statistics courses more than five decades after publication, is why Box-Jenkins is described as a methodology rather than merely a formula (Hyndman, Box-Jenkins modelling, 2001).
Exponential smoothing and modern forecasting methods
Exponential smoothing methods, developed independently by researchers including Robert Brown, Charles Holt, and Peter Winters through the 1950s and 1960s, take a different philosophical stance from ARIMA. Rather than modeling the full autocorrelation structure of the series, they weight recent observations more heavily than older ones, on the logic that the most recent past is usually the best guide to the immediate future. The Holt-Winters method extends simple exponential smoothing to explicitly track trend and seasonality as separate weighted components, updating each one as new data arrives.
Exponential smoothing's appeal is practical: it's fast, requires less tuning than ARIMA, and handles the very common business case of "level plus trend plus seasonality" without much hand-holding. That's why it remains standard in supply chain software and enterprise resource planning systems, even in organizations running far more sophisticated models for their highest-value forecasts.
Modern approaches extend these classical ideas to handle scale and complexity that neither ARIMA nor basic exponential smoothing was designed for. Meta's open-source Prophet library, released in 2017, is built specifically to handle multiple seasonal cycles (daily, weekly, and yearly patterns layered on top of each other), holiday effects, and missing data with minimal manual tuning, aimed at analysts who need reasonable forecasts quickly rather than a statistically optimal model. Neural network architectures, particularly LSTMs (Long Short-Term Memory networks), extend forecasting further by learning nonlinear relationships across very large volumes of related series simultaneously, such as forecasting demand across thousands of retail SKUs (stock-keeping units) at once, sharing learned patterns across products rather than fitting each one in isolation.
Do machine learning models actually beat classical statistics at forecasting?
Not reliably, and not by default. The M4 competition's headline finding was that pure machine learning submissions underperformed simple statistical combination benchmarks, while hybrid methods blending statistical structure with machine learning components won. The lesson researchers drew wasn't that deep learning fails at forecasting, but that raw model complexity doesn't substitute for encoding known structure like seasonality directly into the model (Makridakis et al., 2018).
Why forecasts get less reliable further into the future
Forecast uncertainty compounds with each additional time step for two compounding reasons: earlier prediction errors feed forward into later predictions, and the scope for unmodeled real-world events to intervene grows the further out you project. This isn't a modeling weakness that better algorithms eventually fix, it's a structural property of prediction itself. A one-week electricity demand forecast is typically far more accurate than a one-year forecast built from the identical underlying model, because a year's distance carries vastly more room for weather anomalies, economic shifts, and behavioral changes that the model, trained on the past, has no way to anticipate.
Statistically, this shows up as widening confidence intervals, the range within which the true future value is expected to fall with a given probability. In an ARIMA-type model, forecast error variance grows roughly in proportion to the forecast horizon, which is why professionally built forecasts are almost always presented as a cone that fans outward rather than a single confident line. A retailer forecasting next week's inventory needs might reasonably trust a plus-or-minus 5 percent band; the same retailer forecasting demand a year out should expect that band to be dramatically wider, and a forecast that doesn't visibly widen with distance is one worth being suspicious of.
Why do time series forecasts get less reliable further into the future?
Forecast uncertainty compounds with each additional time step because errors from earlier predictions feed into later ones, and the influence of unmodeled real-world events grows the further out a model projects. A one-week retail forecast is typically far more accurate than a one-year forecast from the identical model, because a year's distance carries far more room for unforeseen shifts the model was never trained to see.
What breaks a time series forecast
Forecasting models assume the future will resemble the statistical structure of the past, an assumption called stationarity in weaker or stronger forms depending on the method. That assumption fails visibly during structural breaks, sudden shifts that change the data-generating process itself rather than just producing an unusually large residual. The clearest recent example is the abrupt 2020 shift in retail, travel, and hospitality demand patterns during the COVID-19 pandemic, when years of stable seasonal structure stopped applying within a matter of weeks, and models trained on pre-2020 history had no basis for anticipating the new regime.
Real, documented forecasting failures tend to cluster around exactly this kind of regime change. Google Flu Trends, a widely cited early example of large-scale predictive analytics, consistently overestimated flu prevalence in the years following its 2008 launch, most severely during the 2012-2013 flu season, in part because changes in people's search behavior over time altered the relationship between search queries and actual flu activity that the original model had been calibrated on (Lazer, Kennedy, King, and Vespignani, "The Parable of Google Flu: Traps in Big Data Analysis," Science, 2014). The failure wasn't that the underlying statistical technique was flawed, it was that the model assumed a stable relationship between search terms and flu incidence that quietly stopped holding as search behavior itself evolved.
Zillow's home-price forecasting algorithm, used to power its Zillow Offers "iBuying" business, offers another widely reported cautionary case. The company shut the program down in late 2021 after its pricing models, trained on historical housing data, struggled to keep pace with an unusually volatile and fast-moving housing market, contributing to Zillow purchasing homes at prices that didn't hold up (Wall Street Journal and CNBC reporting, November 2021). Both cases share the same underlying mechanism: a model built on historical statistical structure meeting a period where that structure genuinely changed, not merely fluctuated.
| Forecasting challenge | What causes it | Typical mitigation |
|---|---|---|
| Structural break | Sudden real-world disruption changes the underlying pattern | Rebuild or retrain the model on post-break data |
| Overfitting | Model captures noise as if it were signal | Cross-validation on holdout time periods |
| Multiple seasonality | Daily, weekly, and yearly cycles overlap | Models like Prophet or TBATS built for layered cycles |
| Outlier distortion | Rare extreme events skew trend and level estimates | Robust decomposition or explicit outlier flagging |
| Non-stationarity | Mean or variance drift over time | Differencing, detrending, or log transformation |
| Concept drift | The relationship between inputs and the target itself changes | Ongoing monitoring and scheduled retraining |
Structural breaks and concept drift are the hardest to catch in advance because, by definition, nothing in the historical data warns a model they're coming.
Evaluating whether a forecast is actually good
A forecast is only as trustworthy as the process used to test it, and the single biggest mistake in evaluating time series models is testing them the same way you'd test an ordinary regression model. Random train-test splits, standard practice elsewhere in machine learning, leak future information into the training set for a time series, because a model can "see" data from after the point it's supposed to be predicting. The correct approach is a rolling-origin or walk-forward validation: train on data up to a point, forecast forward, then advance the training window and repeat, always keeping training strictly earlier in time than testing.
Common accuracy metrics include MAPE (Mean Absolute Percentage Error), which expresses average error as a percentage of the actual value and is intuitive to communicate to non-technical stakeholders, and RMSE (Root Mean Squared Error), which penalizes large errors more heavily than small ones by squaring them before averaging. Neither metric is universally superior; MAPE breaks down when actual values are near zero (dividing by a tiny number inflates the percentage absurdly), while RMSE's sensitivity to large errors is a feature in applications like power grid demand, where a single large miss is much more costly than several small ones, but a distortion in applications where errors of all sizes matter roughly equally.
A well-run forecasting practice also tracks accuracy over time rather than treating a single validated model as a permanent fixture. Given how forecast reliability degrades with structural breaks, organizations that quietly stop checking whether last year's model still fits this year's data are the ones most likely to be blindsided by exactly the kind of regime change that broke Google Flu Trends and Zillow's pricing algorithm.
Comparing the major forecasting model families
| Model family | Data requirements | Interpretability | Typical use case |
|---|---|---|---|
| ARIMA (statistical) | Single series, moderate history, ideally stationary or differenceable | High — coefficients map to clear autoregressive/moving-average effects | Single-series economic and financial forecasting with stable patterns |
| Exponential smoothing / Holt-Winters | Single series, works with shorter history than ARIMA | High — trend and seasonal components are directly visible | Inventory and demand planning at scale, fast automated forecasting |
| Prophet | Single series with clear seasonality and known holidays/events | Medium — components are visualizable but internals are less transparent | Business forecasting with multiple seasonal cycles and irregular calendar effects |
| LSTM / deep learning | Large volumes of related series, longer history preferred | Low — predictions are hard to trace back to specific causes | Large-scale retail SKU forecasting, demand sensing across thousands of related series |
| Hybrid (statistical + ML ensemble) | Varies, often combines outputs of several of the above | Medium — depends on how the ensemble is constructed | High-stakes forecasting where accuracy matters more than a single clean explanation |
Interpretability and data requirements trade off in roughly opposite directions: the models that need the least data to produce a reasonable forecast tend to be the ones you can most easily explain to a stakeholder, while the models that need the most data tend to be the hardest to explain and the hardest to trust blindly.
Why this matters for everyday decisions
Retailers, power grid operators, and hospitals all rely on time series forecasting to allocate resources before demand arrives, not after. Grid operators forecast electricity demand hours and days ahead specifically because power generation capacity can't be switched on instantly, and errors in that forecast carry real costs, either wasted generating capacity sitting idle or a shortfall that risks brownouts. Hospitals use similar forecasting to plan staffing levels and bed capacity around predictable seasonal surges, like the annual rise in respiratory illness admissions each winter.
The common thread across every one of these applications is that the decision has to be made before the outcome is known, which is the entire reason forecasting exists as a discipline rather than simply waiting and reacting. A forecast that arrives after the decision window has closed has zero operational value no matter how statistically sound it is, which is why forecasting systems in production are often judged as much on speed and reliability of delivery as on raw statistical accuracy.
What people get wrong about forecasting
The most common misconception is treating a forecast's central estimate as a guarantee rather than the middle of a probability distribution. A forecast that says "expected demand: 10,000 units" is really saying something closer to "10,000 units is the single most likely outcome, with a wide range of plausible outcomes around it," and organizations that plan inventory or staffing around the point estimate alone, ignoring the width of the surrounding interval, are setting themselves up to be surprised by entirely normal statistical variation.
A second common error is assuming that more sophisticated models are automatically better. As the M4 competition demonstrated, pure deep learning approaches underperformed simpler statistical combinations on a large, diverse benchmark of real series (Makridakis et al., 2018). Complexity is worth its cost only when the added flexibility captures real structure in the data that a simpler model misses, not merely because a more advanced-sounding method is available.
A third error is conflating a model that fits historical data well with a model that will forecast well. A model with enough free parameters can trace almost any historical squiggle closely, but that closeness of fit says nothing about how the model will perform on data it hasn't seen, which is precisely why proper time-respecting validation, not in-sample fit, is the right test of forecasting quality.
The takeaway
Time series forecasting works by separating what's structurally predictable, trend and repeating cycles, from what isn't, then projecting the predictable part forward while being honest about how quickly uncertainty grows with distance. The forecasts that fail hardest are usually the ones that mistake a temporary pattern for a permanent one, ignore how fast confidence should shrink as the horizon extends, or lean on model complexity as a substitute for encoding what's actually known about the data's structure. Good forecasting isn't about eliminating uncertainty, it's about correctly locating where the uncertainty lives and sizing decisions to match it.
Read next:
- Why Outliers Can Change Averages
- What A Confidence Interval Really Means
- How Correlation Differs From Causation
FAQ
Q: What is the difference between trend and seasonality in time series forecasting?
Trend is the long-term direction a series moves in, regardless of timing within a cycle, such as steady year-over-year revenue growth. Seasonality is a repeating pattern tied to a fixed, calendar-driven period, like a weekly, monthly, or yearly cycle, that recurs regardless of the overall trend direction.
Q: Why do forecasts become less accurate the further into the future they predict?
Each additional time step compounds prior forecast error and increases exposure to unmodeled real-world disruptions, so statistical uncertainty and the resulting confidence interval grow wider the further the forecast horizon extends from the last observed data point.
Q: What is ARIMA and why is it still used?
ARIMA (AutoRegressive Integrated Moving Average) is a classical statistical forecasting method formalized by Box and Jenkins in 1970 that models future values based on a series' own past values, its differencing needed for stationarity, and past forecast errors. It remains widely used because it is interpretable, computationally light, and performs well on data with stable, well-defined patterns.
Q: Can time series forecasting predict sudden events like a pandemic or a market crash?
No. Forecasting models assume future patterns will resemble the historical statistical structure they were trained on. Sudden structural breaks caused by unprecedented events fall outside what any model trained on prior data can anticipate, which is why documented forecasting failures like Google Flu Trends and Zillow's home-pricing algorithm both trace back to periods where the underlying data relationships genuinely changed.
Q: Do machine learning models forecast better than classical statistical methods like ARIMA?
Not automatically. The 2018 M4 Forecasting Competition, a large benchmark across 100,000 real series, found that pure machine learning submissions underperformed simple statistical combination methods, while hybrid approaches blending statistical structure with machine learning components performed best overall.
Q: How should a time series forecasting model be tested for accuracy?
Time series models require rolling-origin or walk-forward validation, where training data always precedes test data in time, rather than a random train-test split, which would leak future information into training. Common accuracy metrics include MAPE for percentage-based error and RMSE for penalizing large errors more heavily.
Follow new articles
Add SciHub101 to your feed reader to see new science and technology stories.
About the Author
SciHub101 is an independent science and technology publication founded and edited by Buğra Sözeri, a software engineer and app developer based in Türkiye. AI tools assist with drafting and research. Source documentation in the existing archive is uneven, and articles are being reviewed and corrected. The Editorial Team byline identifies editorial responsibility; it does not certify specialist or independent human review. Where we compare products, anything built by our own team is labelled as such — see the editorial guidelines and About page for how corrections and disclosures work.
Related Articles